The executive committee receives what appears to be an excellent report. The company is generating content in twelve languages. Unit costs have fallen. A campaign that once took three weeks can now be ready in three hours. The number of people using the tool continues to grow month after month.
Everything looks perfect.
Until someone asks the only question that matters:
What business result has all this actually delivered?
In many organisations, the answer is not in the report. Not because data is missing, but because the metrics being tracked prove that AI is being used—not that the investment is working.
One critical point is often overlooked in conversations about enterprise AI adoption. Companies have bought licences, connected platforms, trained teams and announced transformations. Questioning the return now can feel uncomfortable. Yet treating activity as if it were value does not protect the investment; it prevents the organisation from correcting it.
The paradox: almost everyone uses AI, but few can connect it to financial performance
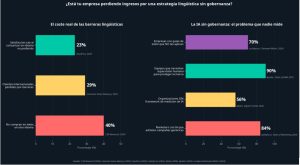
McKinsey’s 2025 global survey shows just how far adoption and value have drifted apart. Eighty-eight percent of respondents said their organisation was regularly using AI in at least one business function. Yet only 39% reported any AI impact on enterprise-wide EBIT and, among those reporting an impact, most placed it below 5% of EBIT [1].
BCG adds a second layer to this paradox. Companies expected to double their AI spend in 2026, from approximately 0.8% to 1.7% of revenue. More than 90% expected to maintain or increase investment even if they did not achieve a return over the following year [2].
The company has not yet demonstrated the return, but it has already decided to keep spending.
This does not prove that AI does not work. It demonstrates something more useful: using a technology, producing work faster and generating financial value are three different things.
| Level | Question it answers | Example indicators |
| Adoption | Is AI being used? | Active users, prompts, words processed, languages covered |
| Productivity | Is a task being completed faster? | Generation time, translation time, documents per hour |
| Business impact | Has the organisation’s result improved? | Total cost, margin, conversion, time to market, incidents, retention, risk |
A workflow can perform exceptionally well in the first two rows without creating any improvement in the third. It may even make it worse.
Why it is so difficult to ask the uncomfortable question
Every major implementation creates internal incentives. There is an executive sponsor, an approved budget, announced targets and expectations to manage. The larger the investment—and the more visible the decision—the harder it becomes to conclude that the programme needs to be scaled back, redesigned or stopped.
Behavioural economics calls this the sunk cost fallacy: the tendency to continue investing in a decision because resources have already been committed, even though those resources cannot be recovered. In an organisation, this rarely appears as an explicit refusal to measure. It takes a subtler form: teams select indicators that make implementation look as if it is progressing.
BCG found that half of surveyed CEOs believed their role could be at risk if AI failed to deliver results. The same study identified a confidence gap: 62% of CEOs trusted the expected return, compared with 48% of non-technology leaders further away from the executive suite [2]. These figures do not prove that anyone is hiding results. They do show that those approving the investment and those experiencing its day-to-day operation may be assessing different realities.
This is where a common habit begins: replacing a difficult question with an easier one.
Instead of asking, “Has conversion increased in Germany?”, teams ask, “How many pages have we generated in German?” Instead of measuring, “Has the total cost to publication fallen?”, they report, “How much has the cost per word decreased?” Instead of checking, “What percentage passes quality control first time?”, they celebrate, “How long does the model take to produce a draft?”
The metric is real. The conclusion is not always.
Translating faster is not ROI
The most common sentence in an AI language business case is also one of the most misleading:
“It used to take three weeks. Now it takes three hours.”
The improvement may be valuable, but it is not yet a return. To turn saved time into value, the organisation must prove what happened next. Was the product launched earlier? Was more useful content published? Did the team use the freed-up capacity for higher-value work? Did labour costs genuinely fall, or was the effort simply shifted to review, coordination and corrections?
IBM reports that around 79% of executives perceive AI-driven productivity gains, but only approximately 29% say they can measure its ROI with confidence [3]. The gap between those figures captures the problem well: a potential operational improvement does not automatically become a financial outcome.
In multilingual workflows, the illusion is especially easy to create because generation is almost instant and highly visible. The downstream costs, by contrast, are distributed across teams: marketing corrects the tone; product identifies strings that do not fit; legal reviews claims; support answers questions the content failed to resolve; and the local market owner rewrites messages that do not work in their market.
The machine finished in three hours. The company may never have finished.
The missing metric: cost per publishable asset
For years, cost per word was the dominant translation metric. In a LangOps environment, that figure is no longer enough. It may describe the price of one stage, but not the cost of obtaining a usable result.
The business-relevant unit is the cost per publishable asset: what it costs to produce a web page, campaign, manual, interface or communication that can go to market, fulfil its purpose and avoid creating disproportionate downstream debt.
At a minimum, this cost should include the model licence or consumption cost, supporting platforms, integration, data preparation, workflow management, human review, corrections, rework, incidents and maintenance. Where appropriate, it should also include an estimate of risk and opportunity cost.
A simple way to express it is:
Cost per publishable asset = generation + technology + integration + management + review + correction + incidents + maintenance
This perspective changes the conversation. A workflow that reduces generation costs by 80% may still be worse business if it triples review time, increases critical errors or produces content that does not convert. Equally, a workflow with apparently expensive human review can generate a higher return if it reduces rework, accelerates regulatory approval or protects a high-value campaign.
RWS identifies another obstacle: the information needed to calculate this return is often fragmented. Marketing owns engagement and conversion data; product owns launch dates; compliance owns incidents; finance owns invoices; and the language team owns volume and quality information. Each dataset tells part of the story, but none proves value on its own [5].
Measuring LangOps ROI is therefore not about adding another tool to the workflow. It is about connecting data the company already has but keeps separate.
The metrics that can make failure look good
None of the conventional metrics is useless. The mistake is interpreting them out of context.
| Common metric | What it proves | What it does not prove |
| Cost per word | The unit price of one stage | The total cost of usable content |
| Words or assets per hour | Raw speed | Quality, relevance or commercial performance |
| Number of languages | Theoretical coverage | Effective presence or suitability in each market |
| Generation time | Duration of initial production | Total time to approval and publication |
| Active users | Internal adoption | Economic value created |
| Hours saved | Potential capacity released | How that capacity was used |
| Isolated linguistic quality score | Accuracy against one criterion | Whether the content achieves its business purpose |
Even an apparently advanced metric can mislead when used alone. Time to Edit, for example, measures how long it takes a person to bring automated output up to the required standard and can be a valuable system-efficiency indicator [6]. But a text requiring little editing may still fail to rank, fail to convert, or be unsuitable for the regulatory purpose it must serve.
Useful measurement combines process, outcome and risk.
The LangOps dashboard leadership should see
Not every company needs the same dashboard, but any multilingual AI implementation should be able to answer eight questions.
| Dimension | Recommended indicator | Leadership question |
| Cost | Total cost per publishable asset | What does it really cost to obtain usable content? |
| Efficiency | Total time from request to publication | Are we accelerating the business—or just one stage? |
| Human effort | Review minutes per asset or per 1,000 words | Is AI removing effort or shifting it elsewhere? |
| Quality | Error rate and severity; first-pass yield | What percentage passes control first time? |
| Market | Conversion, engagement, visibility or usage by market | Does the content fulfil the purpose for which it was created? |
| Customer | Tickets, complaints or abandonment attributable to language | Is automation creating downstream friction? |
| Risk | Compliance, privacy or brand incidents | What exposure does the workflow create or prevent? |
| Learning | Repeated corrections and performance trends | Is the system improving or reproducing the same failures? |
First-pass yield—the percentage of assets that pass quality control first time—deserves particular attention. A company can generate ten times more content with AI and, at the same time, overwhelm reviewers if almost no assets arrive ready to publish. In that case, generation capacity has increased, but real publishing capacity has not.
Metrics should also be separated by content type and risk level. It makes no sense to assess a low-impact product description, a brand-defining campaign, safety instructions and a regulatory document against the same threshold. Efficiency emerges when control is proportional to risk—not when the same workflow is applied to everything.
The 95% figure: useful as a warning, dangerous as a slogan
The preliminary 2025 report The GenAI Divide, produced by MIT Project NANDA, stated that 95% of the organisations studied were not achieving measurable returns from their generative AI initiatives and that only 5% of certain enterprise tools were successfully reaching production [4]. It is a striking figure and has been widely repeated.
It also requires context. The report is based on a review of more than 300 public initiatives, interviews with 52 organisations and a survey of 153 executives. The authors themselves caution that some findings are directional, samples vary by category and definitions of success are not homogeneous [4].
The 95% should therefore not be used as a universal failure rate for all enterprise AI. Its value lies in its explanation of a pattern: projects that are not embedded in real work, do not learn from corrections and are not evaluated against business outcomes tend to remain demonstrations or pilots.
The LangOps lesson is clear: the model matters less than the system it is embedded in.
How to design a test that can survive the CFO
A serious ROI test does not need to begin with a major transformation programme. It can be built around one content type, one market and one testable hypothesis.
First, define the outcome before selecting the tool. “Use AI to translate the knowledge base” is not an objective. “Reduce time to publication by 20% without increasing support incidents or critical errors” is.
Then establish a baseline for the current process: total cost, end-to-end time, human effort, approval rate, incidents and market outcome. Without that initial picture, any later improvement is merely an opinion.
Next, compare two workflows over a sufficiently long period using equivalent content. The calculation must include all costs—not only the easiest to obtain. The organisation should also agree the decision criterion in advance: what result will justify scaling, what will require redesign and what will justify stopping the test.
| Step | Required decision | Error it prevents |
| 1. Select the case and market | What business result are we seeking? | Implementing technology without an objective |
| 2. Set the baseline | How does the current process work and what does it cost? | Claiming improvement without comparison |
| 3. Design the comparison | Which two workflows are we assessing, and for how long? | Confusing non-equivalent cases |
| 4. Include the total cost | What work and risk emerge after generation? | Inflating apparent savings |
| 5. Measure the outcome | What happened in publication, customer experience and market performance? | Stopping at activity metrics |
| 6. Apply an exit criterion | Do we scale, redesign or stop? | Turning a test into mandatory adoption |
The final step is the most important. An implementation with no exit criterion is not an experiment; it is a decision made in advance.
Measure first, redesign second
This is where LangImpact differs from a provider that simply sells more translation capacity.
LangScore establishes a baseline and audits the outcome of multilingual content. It turns impressions such as “it looks right” or “it sounds reasonably good” into a structured evaluation of consistency, terminology, voice, suitability and risk. That measurement is not ROI in itself, but it provides the evidence needed to calculate the cost of obtaining a usable asset and identify where value is being lost.
LangFlow acts on what measurement reveals. It redesigns the workflow to determine what should be automated, what context AI needs, where people should intervene, which rules apply to each content type, and how learning is fed back into the system. The objective is not to add human review everywhere, but to use it where risk and value justify it.
The sequence matters: measure first; redesign second. This allows the organisation to avoid both abandoning its AI investment and defending it on faith. It can preserve what works, correct what destroys value and stop what makes no business sense.
The question that should close the next meeting
The true return on an AI-enabled multilingual strategy is not expressed in words generated or seconds saved. It is expressed in publishable assets, markets served, customers converted, incidents prevented and risks controlled.
The next time a report announces that AI has multiplied output and lowered unit cost, ask three questions:
What does it cost to obtain a genuinely publishable asset? What result does it generate? What risk does it add?
If the dashboard cannot answer them, the organisation is not measuring the return on its AI.
It is measuring activity.
References
[1] McKinsey (2025). The State of AI in 2025: Agents, Innovation, and Transformation. https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai-2025
[2] Boston Consulting Group (2026). As AI Investments Surge, CEOs Take the Lead — BCG AI Radar 2026. https://www.bcg.com/publications/2026/as-ai-investments-surge-ceos-take-the-lead
[3] IBM (2026). How to Maximize AI ROI in 2026. https://www.ibm.com/think/insights/ai-roi
[4] MIT Project NANDA (2025). The GenAI Divide: State of AI in Business 2025. https://mlq.ai/media/quarterly_decks/v0.1_State_of_AI_in_Business_2025_Report.pdf
[5] RWS (2025). How to Measure Localization ROI in Enterprise Programs. https://www.rws.com/blog/how-to-measure-localization-roi-in-enterprise-programs/
[6] Translated. The ROI of AI Translation: Measuring Business Impact. https://translated.com/resources/the-roi-of-ai-translation-measuring-business-impact